Scientific Rigor in Cross-Sectional Modeling
Every prediction is the output of a documented pipeline. Data ingestion, feature
engineering, model training, and signal generation each follow protocols designed to
prevent overfitting and ensure reproducibility.
Discuss methods
Four principles guide every architectural decision we make about model design, training procedures, and deployment practices.
Research Pipeline Overview
From raw market data to ranked forecasts, each stage produces auditable outputs with explicit assumptions, documented limitations, and version-controlled parameters.
Alternative Data Ingestion
Aggregate market microstructure, fundamental filings, and alternative sources into unified panels with automated anomaly detection and outlier flagging.
Economically Grounded Features
Transform raw inputs into factors validated against academic literature. Each feature is tested for predictive power using proper cross-sectional regression techniques.
Ensemble Model Training
Fit multiple architectures with walk-forward validation. Regularization is calibrated to respect cross-sectional correlation structure rather than assuming independence.
Signal Deployment
Generate ranked forecasts with confidence intervals. Monitor for distribution shift and trigger retraining when statistical tests detect regime change.
Evolution of Our Methodology
-
01
Classical Factor Models
Initial research focused on cross-sectional linear factor models with Fama-MacBeth regression and portfolio sorts. These methods provided interpretable baselines but lacked the capacity to capture nonlinear interactions between features.
-
03
Deep Learning Architectures
Deployed neural networks designed for panel data with entity embeddings and temporal attention. Addressed look-ahead bias through careful train-validation splitting aligned with calendar time rather than random sampling.
02
Gradient Boosting Integration
Introduced tree-based ensembles for nonlinear feature interactions. Improved predictive accuracy but introduced opacity. Began developing SHAP-based interpretability tools to maintain transparency requirements.
04
Transformer Models
Adopted transformer architectures for capturing long-horizon temporal dependencies. Attention mechanisms now identify which historical periods are most relevant for current forecasts, with economic constraints embedded in the architecture.
05
Regime-Adaptive Ensembles
Current production systems combine multiple architectures with online regime detection. Models switch automatically between configurations optimized for different market correlation structures, reducing drawdowns during transitions.
Research and Engineering Leadership
The individuals responsible for model architecture, data infrastructure, and validation
frameworks. Each contributes directly to the codebase and research pipeline.
-
Dr. Eleanor Whitfield
Head of Quantitative Research
Former academic with publications in cross-sectional asset pricing and machine learning. Oversees model architecture decisions and validation protocols. Spends most of her time debugging production failures rather than designing new features.
-
Dr. Sarah Chen
Senior Financial Economist
Expert in empirical asset pricing and factor model design. Validates that every feature has a defensible economic rationale before it enters the training pipeline. Maintains the library of academic papers that inform model design.
-
Robert Vasquez
Data Infrastructure Lead
Responsible for the ingestion pipeline that processes millions of records daily. Built the anomaly detection system that flags data quality issues before they contaminate model inputs. Previously worked in high-frequency trading infrastructure.
-
Dr. Amara Osei
Senior Statistician
Designs the statistical tests used for regime detection and model comparison. Her work on block cross-validation for panel data is used throughout the research pipeline to prevent overfitting in time-series contexts.
-
David Lin
Alternative Data Specialist
Sources and evaluates non-traditional data sets for predictive power. Maintains relationships with data vendors and runs the experiments that determine whether a new data source justifies integration into the production pipeline.
James Okonkwo
Lead Machine Learning Engineer
Specializes in deep learning systems for structured data. Built the training infrastructure that prevents data leakage in walk-forward validation. Previously worked on recommender systems before applying those lessons to financial panels.
Dr. Elena Petrov
Research Scientist, Interpretability
Develops methods for decomposing neural network predictions into economically meaningful components. Her tools allow portfolio managers to understand why specific securities received particular rankings on any given day.
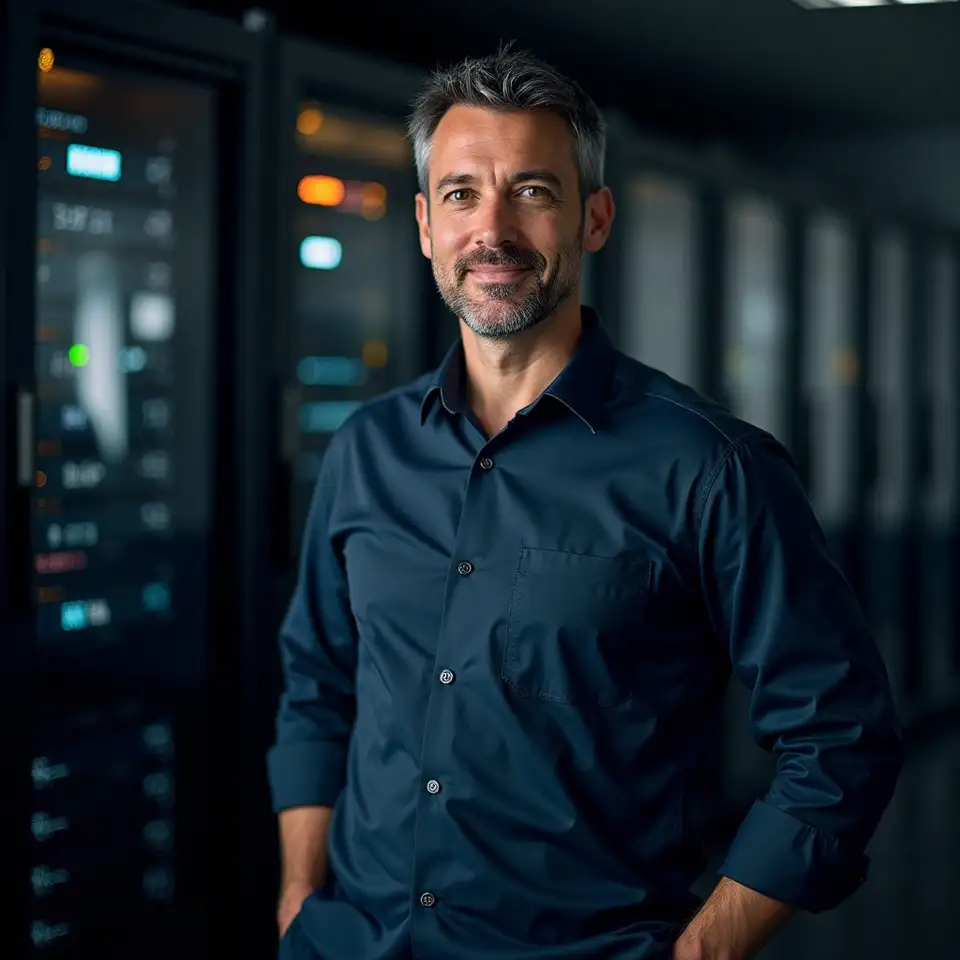
Michael Thornton
Production Engineering Manager
Ensures that research models can be deployed reliably at scale. Built the monitoring systems that detect when model performance degrades and trigger automated alerts for human review.
Review Our Technical Documentation
Whitepapers
Detailed descriptions of model architectures, training procedures, and validation frameworks. Each document includes mathematical notation, pseudocode, and references to the academic literature that informed design decisions.
Research Notes
Short-form analyses of specific methodological questions, failure modes, and experimental results. Updated monthly with findings from ongoing research projects and production monitoring.
Code Samples
Annotated examples of API usage, feature engineering pipelines, and backtesting configurations. Designed to help quantitative researchers integrate our signals into existing workflows with minimal friction.
Consultation
Direct access to the research team for questions about methodology, implementation details, or custom model adaptations. Responses typically arrive within one business day from the individual who wrote the relevant code.